vLLM & SGLang Engineering: End-to-End LLM Serving
Dr. Sreedath Panat
MIT PhD | Vizuara Co-founder
Dr. Rajat Dandekar
Vizuara Co-founder | Purdue PhD
This course is popular
7 people enrolled last week.
Benchmark, tune and deploy LLMs with vLLM and SGLang
Every AI product pays for every token it generates. Most of the industry serves open models like Llama, Qwen and DeepSeek on vLLM or SGLang. This course teaches you to benchmark, tune and deploy both, so you can make that bill smaller and defend every choice with numbers.
Across twelve live, hands-on lectures, lead instructor Dr. Sreedath Panat takes you from vLLM V1 and SGLang SRT internals to structured outputs, cache and scheduler tuning, quantization, multi-GPU serving, speculative decoding and production deployment. He is joined by Vizuara co-founders Dr. Raj Dandekar and Dr. Rajat Dandekar. Inference fundamentals are covered in self-paced pre-work.
Build one growing repository: a shared benchmark harness, tuned deployments on both engines, and quantized checkpoints. For your capstone, benchmark the same model on both, deploy your chosen engine on Kubernetes with routing, metrics and autoscaling, and defend the choice using latency, throughput and cost per million tokens.
Seven weeks. Twelve two-hour live sessions. Recordings, code, notes and practical materials included.
What you’ll learn
Benchmark, tune and deploy both vLLM and SGLang, then choose the right engine using measured latency, throughput and GPU cost.
Trace vLLM V1/PagedAttention and SGLang SRT/RadixAttention from HTTP request to generated tokens.
Build APIs with streaming, LoRA, structured output and tools; write SGLang programs with gen, select and fork.
Run one reproducible harness against both engines: TTFT, TPOT, inter-token latency and throughput under concurrent load.
Use torch profiler and Nsight to investigate bottlenecks before tuning.
Tune vLLM prefix caching and SGLang radix caching, overlap scheduling, chunked prefill, attention backends and CUDA graphs.
Produce FP8 and INT4 checkpoints with llm-compressor; compare quality, memory and latency on both engines against BF16.
Compare tensor, pipeline, data and expert parallelism on both engines, measuring multi-node communication and MoE scaling.
Measure EAGLE, MTP and DSpark speculation and prefill/decode disaggregation using vLLM KV connectors and SGLang with Mooncake.
Deploy your chosen engine on Kubernetes with cache-aware routing, Prometheus metrics, autoscaling and failure handling.
Compare both engines on one workload; present p50/p99 latency, throughput, cost per million tokens and a migration plan.
Learn directly from expert instructors
Dr. Sreedath Panat
MIT PhD and Vizuara co-founder teaching practical LLM systems.

Dr. Rajat Dandekar
Vizuara Co-founder | Purdue PhD | Teaching engineers to build AI systems
Dr. Raj Dandekar
Vizuara co-founder | MIT PhD | GPU, inference and kernel engineering educator
Who this course is for
ML engineers who have run models on a GPU and want to benchmark, optimize and deploy reliable LLM serving systems.
Backend and infrastructure engineers building OpenAI-compatible endpoints, GPU deployments and production observability.
AI builders who want to read, tune and compare the vLLM and SGLang codebases.
Prerequisites
Transformer basics and comfort in a terminal
Know how attention and text generation work. You need not be a Python expert; coding agents help with code. Pre-work covers fundamentals.
What's included
Live sessions
Learn directly from your instructors in a real-time, interactive format.
Lifetime access
Go back to course content and recordings whenever you need to.
Community of peers
Stay accountable and share insights with like-minded professionals.
Certificate of completion
Share your new skills with your employer or on LinkedIn.
Fundamentals pre-work
Self-paced inference fundamentals videos before week one, so live sessions focus on vLLM and SGLang code and experiments.
Reusable engineering toolkit
A shared benchmark harness, configs and deployment templates for both engines, plus lecture notebooks and cloud-GPU scripts.
Notes, assignments and quizzes
Handwritten notes, slides, assignments and interactive quizzes to reinforce the concepts behind each experiment.
Production capstone and showcase
Benchmark both engines, deploy your chosen endpoint, and present the SLO and cost analysis. Includes a capstone showcase page.
Maven Guarantee
Your purchase is backed by the Maven Guarantee.
Course syllabus
12 live sessions • 12 lessons
Live sessions
4 hrs / week
Tuesdays and Thursdays, 7:30 to 9:30 AM IST (in the US: Mondays and Wednesdays, 6 to 8 PM PT / 9 to 11 PM ET), November 10 to December 17, 2026. Twelve live lectures over six weeks, totaling 24 hours. Dr. Sreedath Panat leads the course, joined by Dr. Raj Dandekar and Dr. Rajat Dandekar. Recordings included.
Week 1
Inside both engines
Nov
11
Session 1
Week 2
Nov
18
Session 2
Serving on each engine
Free resources
Testimonials
It’s been a long time since I was in an academic setup, and I must say this course was extremely well designed and very practical. Sreedath was always well prepared, and the sessions were so engaging that I attended every single one without fail. The discussions around research papers and live sessions on Transformers and the ecosystem that were developed around like LLMs, VLMs, nanoVLM and TimeSformer were particularly insightful. I really loved the way concepts were explained, the assignments, and the overall curriculum.
Ajay Sadhu
App Developer, NeonQ · Transformers for Vision / Computer VisionThe program focused on practical engineering challenges in 5D parallelism and GPU systems, which made the learning experience both rigorous and deeply insightful. Working through real resource constraints and system-level trade-offs provided a much clearer understanding of how large-scale GPU workloads are actually designed and optimized. What stood out most was the depth of the explanations. Raj Sir walked through the architecture, parallelism strategies, and engineering decisions in a way that connected theory with real implementation details. The sessions were exceptionally valuable for building a deeper, more practical perspective on GPU engineering.
Hrishabh Gupta
Staff Software Engineer, Confluent · 5D Parallelism / GPU SystemsA magnificent course, the lecturer demonstrates exceptional insight and communicates complex ideas with remarkable clarity.
Eran Ben Artzy
Research Engineer · VLA and World ModelsI am thoroughly impressed and enlightened with the Gen AI fundamental course. I have done several courses but none of them explain the fundamentals of Gen AI at a 'molecular' level like this one. I am yet to watch all the videos but I have seen Vizuara's YouTube videos which attracted me to this course.
Prashant Hardikar
Infosys Limited USA · Generative AI Fundamentals / Foundation of AI ModelsIn the corporate world, no one really enjoys working "overtime." Interestingly, most of your lectures extended beyond the scheduled time, yet I was pleasantly surprised to find my interest fully intact throughout. This is a true reflection of the quality of your teaching pedagog, something you consistently bring, not only in your workshops but also through your YouTube channel playlists.
Shishir
Senior Data Science Associate, ZoomRx Healthcare Technology Solutions Private Limited · Production-grade RAG PipelineDr. Raj Dandekar is an exceptional teacher. I attended his ten-day bootcamp, Vizuara AI Agents Bootcamp, and wholeheartedly recommend it to anyone looking to dive deep into AI with expert guidance. The clarity, depth, and real-world relevance of his teaching set him apart. I’m so impressed that I plan to enroll both my kids in his training after they complete their 12th standard. Don’t look anywhere else, he’s the best.
Vardhan Kale
Sr Product Manager · AI Agents Bootcamp
Inside the engines that serve almost every open LLM
A 6-minute film on how vLLM and SGLang turn a request into tokens on real GPUs.
Your instructors wrote the book on building LLMs from scratch
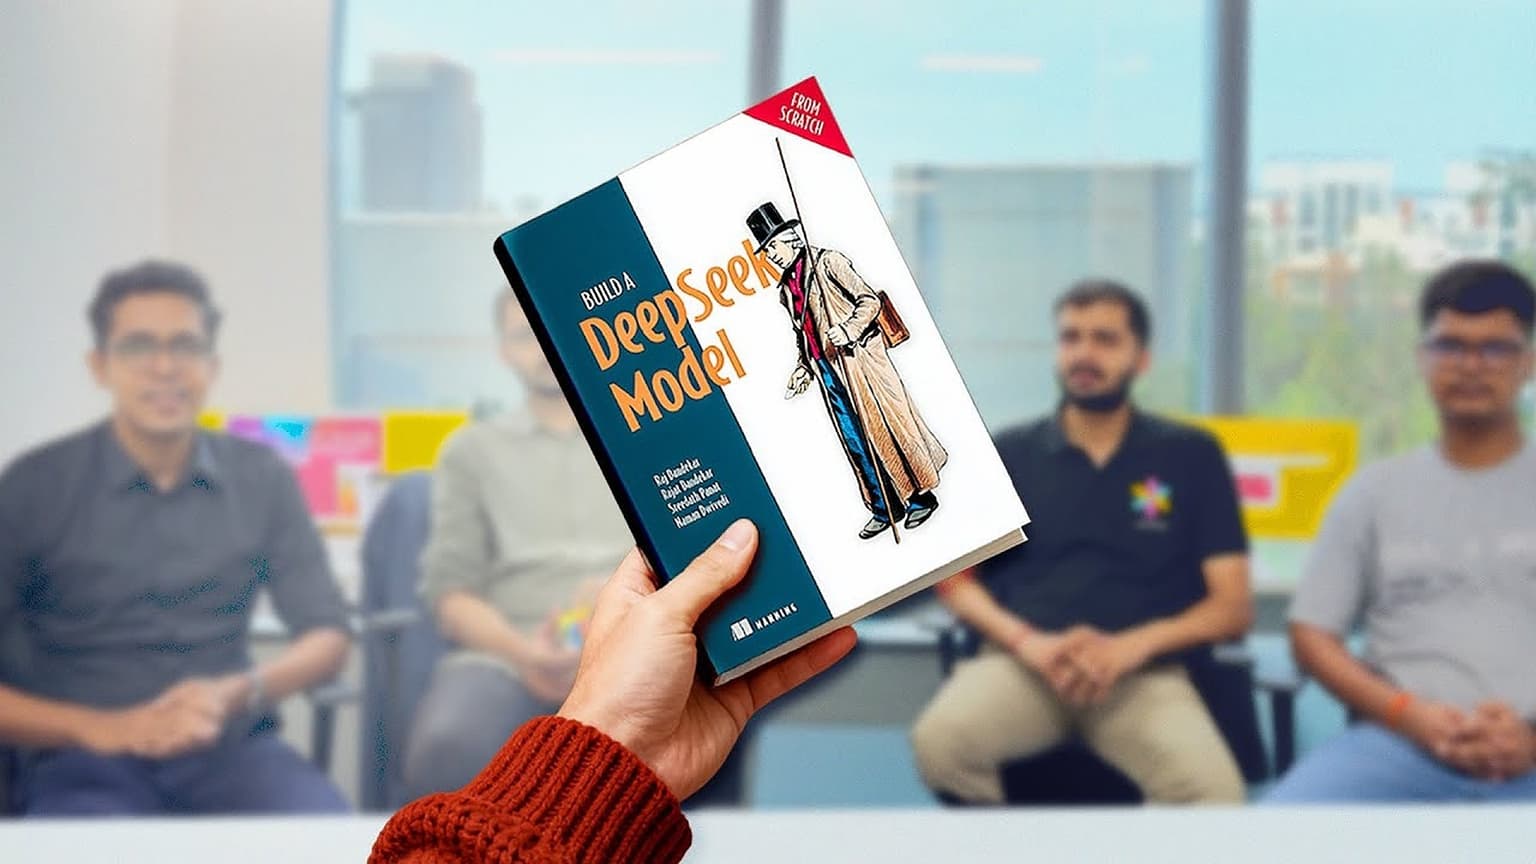
Build a DeepSeek Model (From Scratch), Manning Publications, co-written by the Vizuara team.
Frequently asked questions
Maven for Teams
Reimbursement
Get your company to pay
Everything L&D needs: email template, receipts, and certificate of completion.
Get reimbursedTeam discount
Learn with your teammates
Save 20%+ when 2 or more teammates enroll in the same cohort.
Save 20%+ with a teamPrivate cohort
Run a cohort for your org
A dedicated cohort with a custom schedule and curriculum, tailored to your team.
Book a private cohort$799
USD