

Free Lesson
The unreasonable effectiveness of BM25 for agentic search
Part of The Future of AI Search
60 min
Oct 30, 2026 11:00 AM
By continuing, you agree to Maven's Terms and Privacy Policy.
What you'll learn
Retrieval, not reasoning, is what holds most agents back
Agents given the right evidence answer hard questions well, but finding that evidence in ~1B tokens is the hard part.
Why “BM25 is just a baseline” breaks down with agents
How default settings and evaluation harnesses can make lexical retrieval look weak, and what changes when you fix them.
Agents search like power users, and why BM25 rewards this
Why explicit and expressive queries benefit agents, allowing them to draw on what they know to refine as neede.
Design the harness, then measure the whole task
How the way you expose search shapes results & token cost, and why end-to-end task success beats single-query metrics.
Why this topic matters
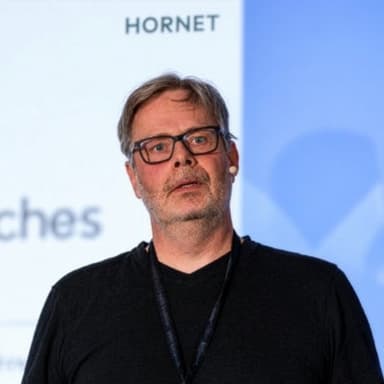
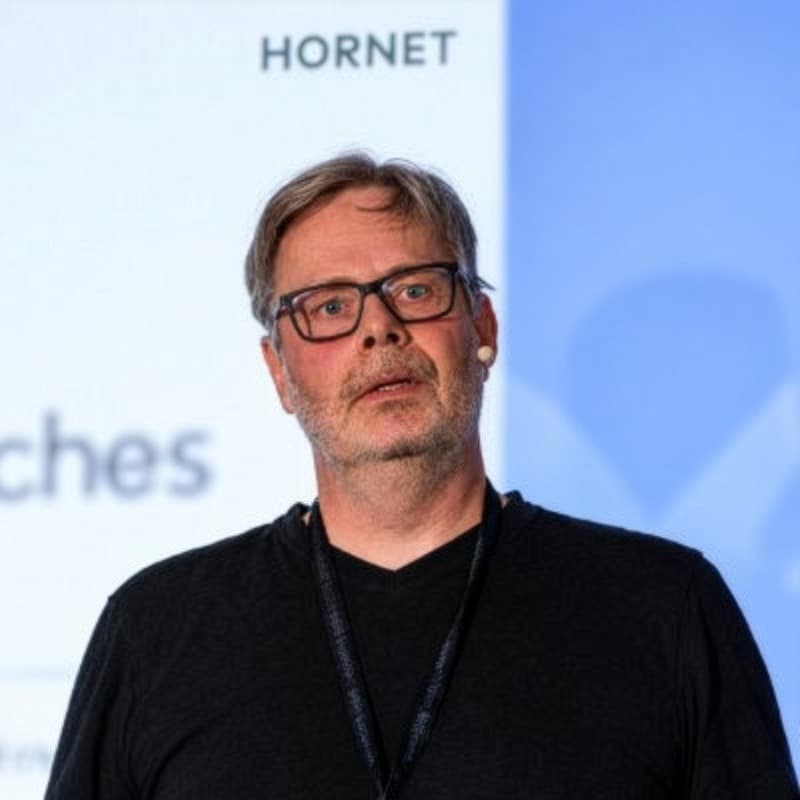
Grep became a core retrieval tool for coding agents. Jo Kristian Bergum, CEO of Hornet, argues that BM25 serves a similarly powerful function for search agents (in contrast with popular vector embedding approaches). GPT-5 is a very capable searcher, writing long, precise queries with exact phrases in ~98% of sessions. Jo will walk through the unreasonable effectiveness of BM25 for agentic search, and why this 30-year old algorithm often wins.