Free Resources for Basic AI Evals
Matt Barney
PhD, Motorola Master Black Belt, ex-Infosys VP, 3 patents, LLM-as-Judge science
What makes it valuable
Ten free useful readings by the people who teach the basics. After each one, a short note says what that reading leaves open. Those gaps are what our advanced AI Evals class teaches. You get a reading path and a map of gaps, not a link list.
What you will gain
Name the first three basic judge biases (position, length, self-preference) and know which reading shows each one.
See why agreement with a human is a statistic with traps, and when Kappa deceives.
Learn why an eval score needs an uncertainty interval
Learn what a Rasch measurement model adds over pass rates: items, judges and performers on one scale.
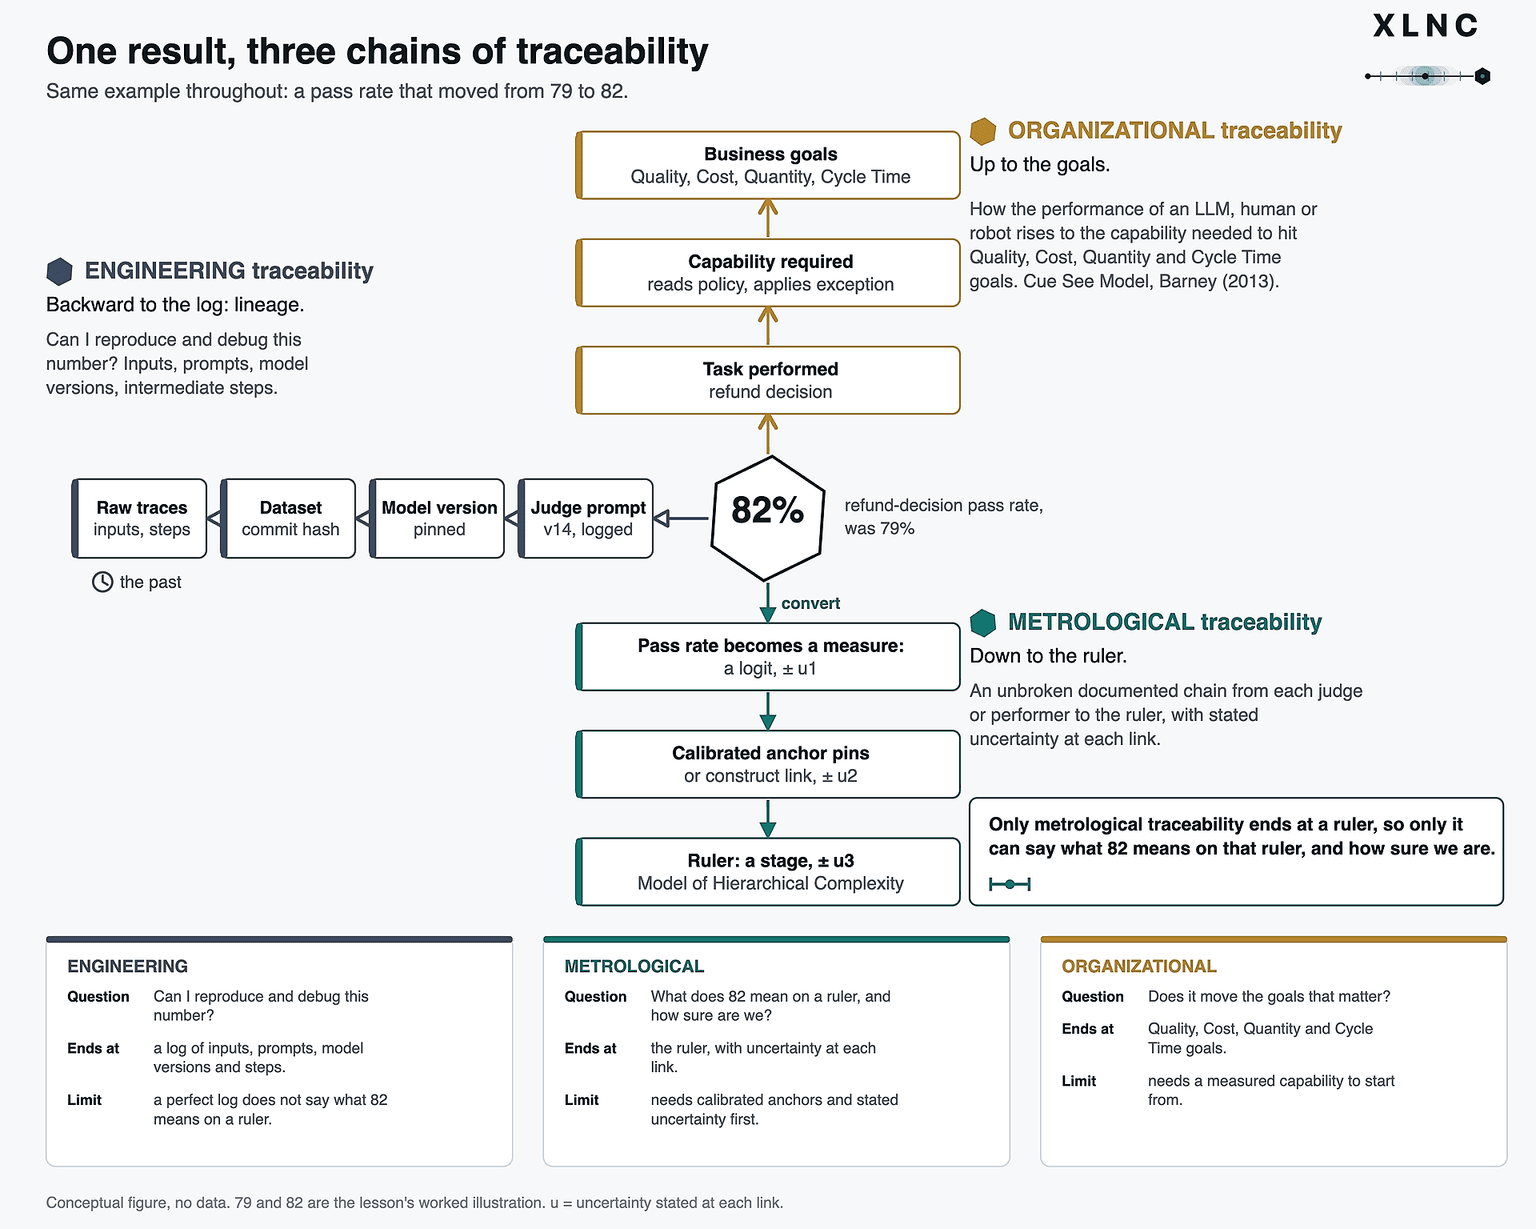
Tell three kinds of traceability apart (engineering, metrological, organizational) and say which your team has today.
Finish with a readiness check you can answer in your own words.
Problems it solves
“Our LLM judge says 82%, and we cannot tell if that is real.”
“We re-ran the judge and got a different result.”
“We do not know which of the many eval articles to read first.”
“Our logs show what ran, but not whether the score means anything.”
“We cannot say how sure we are when we report a score.”
Why it matters
A judge’s verdict often decides what ships, what is fixed and what is trusted. When the verdict is wrong, the cost can be a missed defect, a wasted budget or a late decision. Most teams can still fix this: a few ideas, read in the right order, change what you ask of your own eval. The guide helps you spend care where a wrong verdict costs the most, and keep it simple where it does not.
Who this is for
Engineers, product leads, data scientists and quality leaders who use an LLM to judge AI output, or who will be asked to defend that judge’s verdict. New to evals? The guide includes an optional free on-ramp of about 2 hours.
How to use
Before the 1-hour Lightning Lesson: recommended. About 20 minutes. The readings are optional for the lesson.
Before courses and workshops: required. Read the seven marked required readings (about 5.5 hours) and pass the readiness check. All ten readings take about 8 hours.
Bring one judge you use today, with a few dozen of its ratings, and the one failure that would hurt your users most.
An example of what is missing from basic courses