Life of a Model: Build, Teach, Tune, Ship
Follow an AI models journey from text to real users in four FREE lessons: 1. Build a model (pre-training) 2. Teach a model (post-training) 3. Tune a model (fine-tuning, distillation, quantization) 4. Ship a model to production (evals, inference, deployment)
Tue Nov 3·6:30 PM UTC
🏗️ Build a Model: Pre-Training and GPU Clusters
Every AI assistant you use starts as a base model trained to predict the next token. Understanding pre-training explains what LLMs know, why they hallucinate, and why frontier models cost hundreds of millions to build. If you make decisions about AI products, budgets, or vendors, this is the foundation. A base model knows a lot but doesn't know how to behave, and that gap drives everything that comes next.
You'll learn from
Priyanka Vergadia
Visual Product Storyteller | Built & Shipped AI at Google & Microsoft
Thu Nov 5·5:00 PM UTC
Build Real-Time Voice Agents: Architecture Walkthrough
A chat window forgives a slow answer. A phone call does not. Once an agent joins a live conversation, half a second of silence feels broken, and a wrong action lands while the caller is still on the line. Text-agent habits don’t carry over. This walkthrough with Deepgram's Kris Efland, VP of Engineering covers the architecture choices that decide whether a voice agent earns trust or loses the caller.
You'll learn from
Priyanka Vergadia
Visual Product Storyteller | Built & Shipped AI at Google & Microsoft
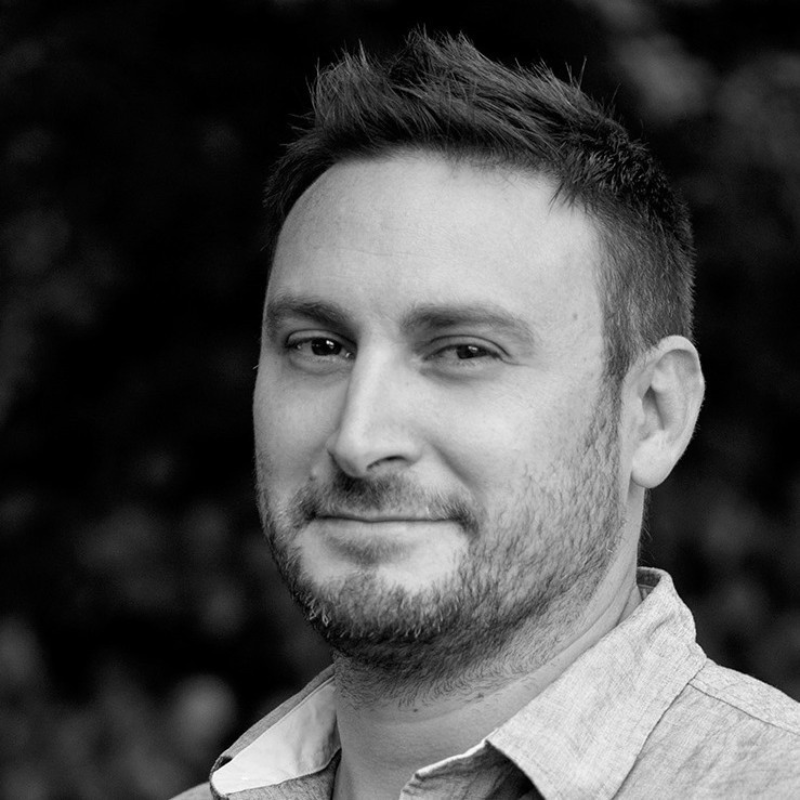
Kris Efland
VP of Engineering, Deepgram
Fri Nov 6·7:00 PM UTC
🧑🏫 Teach a Model: Post-Training, RLHF, and Reasoning
A base model can complete text, but it can't reliably answer a question, refuse a harmful request, or work through a hard problem. Post-training is where those behaviors are shaped, and it's why ChatGPT, Claude, and Gemini feel so different from raw models. It's also where quality and safety trade-offs get decided, which makes it essential knowledge for anyone judging or choosing a model.
You'll learn from
Priyanka Vergadia
Visual Product Storyteller | Built & Shipped AI at Google & Microsoft
Mon Nov 9·7:00 PM UTC
⚙️ Tailor a Model: Fine-Tuning, LoRA, and Quantization
Most teams never train a model from scratch, but almost every team needs to adapt one and run it affordably. Fine-tuning fits the model to your task, while distillation and quantization fit it to your budget. These choices decide whether an AI feature stays a demo or becomes a product you can serve at a cost that makes business sense.
You'll learn from
Priyanka Vergadia
Visual Product Storyteller | Built & Shipped AI at Google & Microsoft
Wed Nov 11·7:00 PM UTC
🚀 Launch a Model: Evals, Inference, and Deployment
A model isn't done when training ends. Evals tell you if it's good, and inference and deployment decide whether anyone can actually use it. Latency, cost per token, and reliability make or break an AI product in the real world. This lesson closes the loop: production feedback becomes the data that starts the next life of the model.
You'll learn from
Priyanka Vergadia
Visual Product Storyteller | Built & Shipped AI at Google & Microsoft
Mon Nov 16·7:00 PM UTC
Fine-Tune Open Models Without Running GPU Ops: Crusoe
Customizing an open model has meant renting a cluster and paying for idle GPUs, so most teams default to frontier APIs. A smaller open model trained on your own data can beat a frontier model on cost, latency, and task accuracy, and a NeoCloud like Crusoe now runs the whole loop, dataset to endpoint, without cluster ops. This session runs it live, covers what production demands beyond a demo, and looks at where post-training is heading.
You'll learn from
Priyanka Vergadia
Visual Product Storyteller | Built & Shipped AI at Google & Microsoft
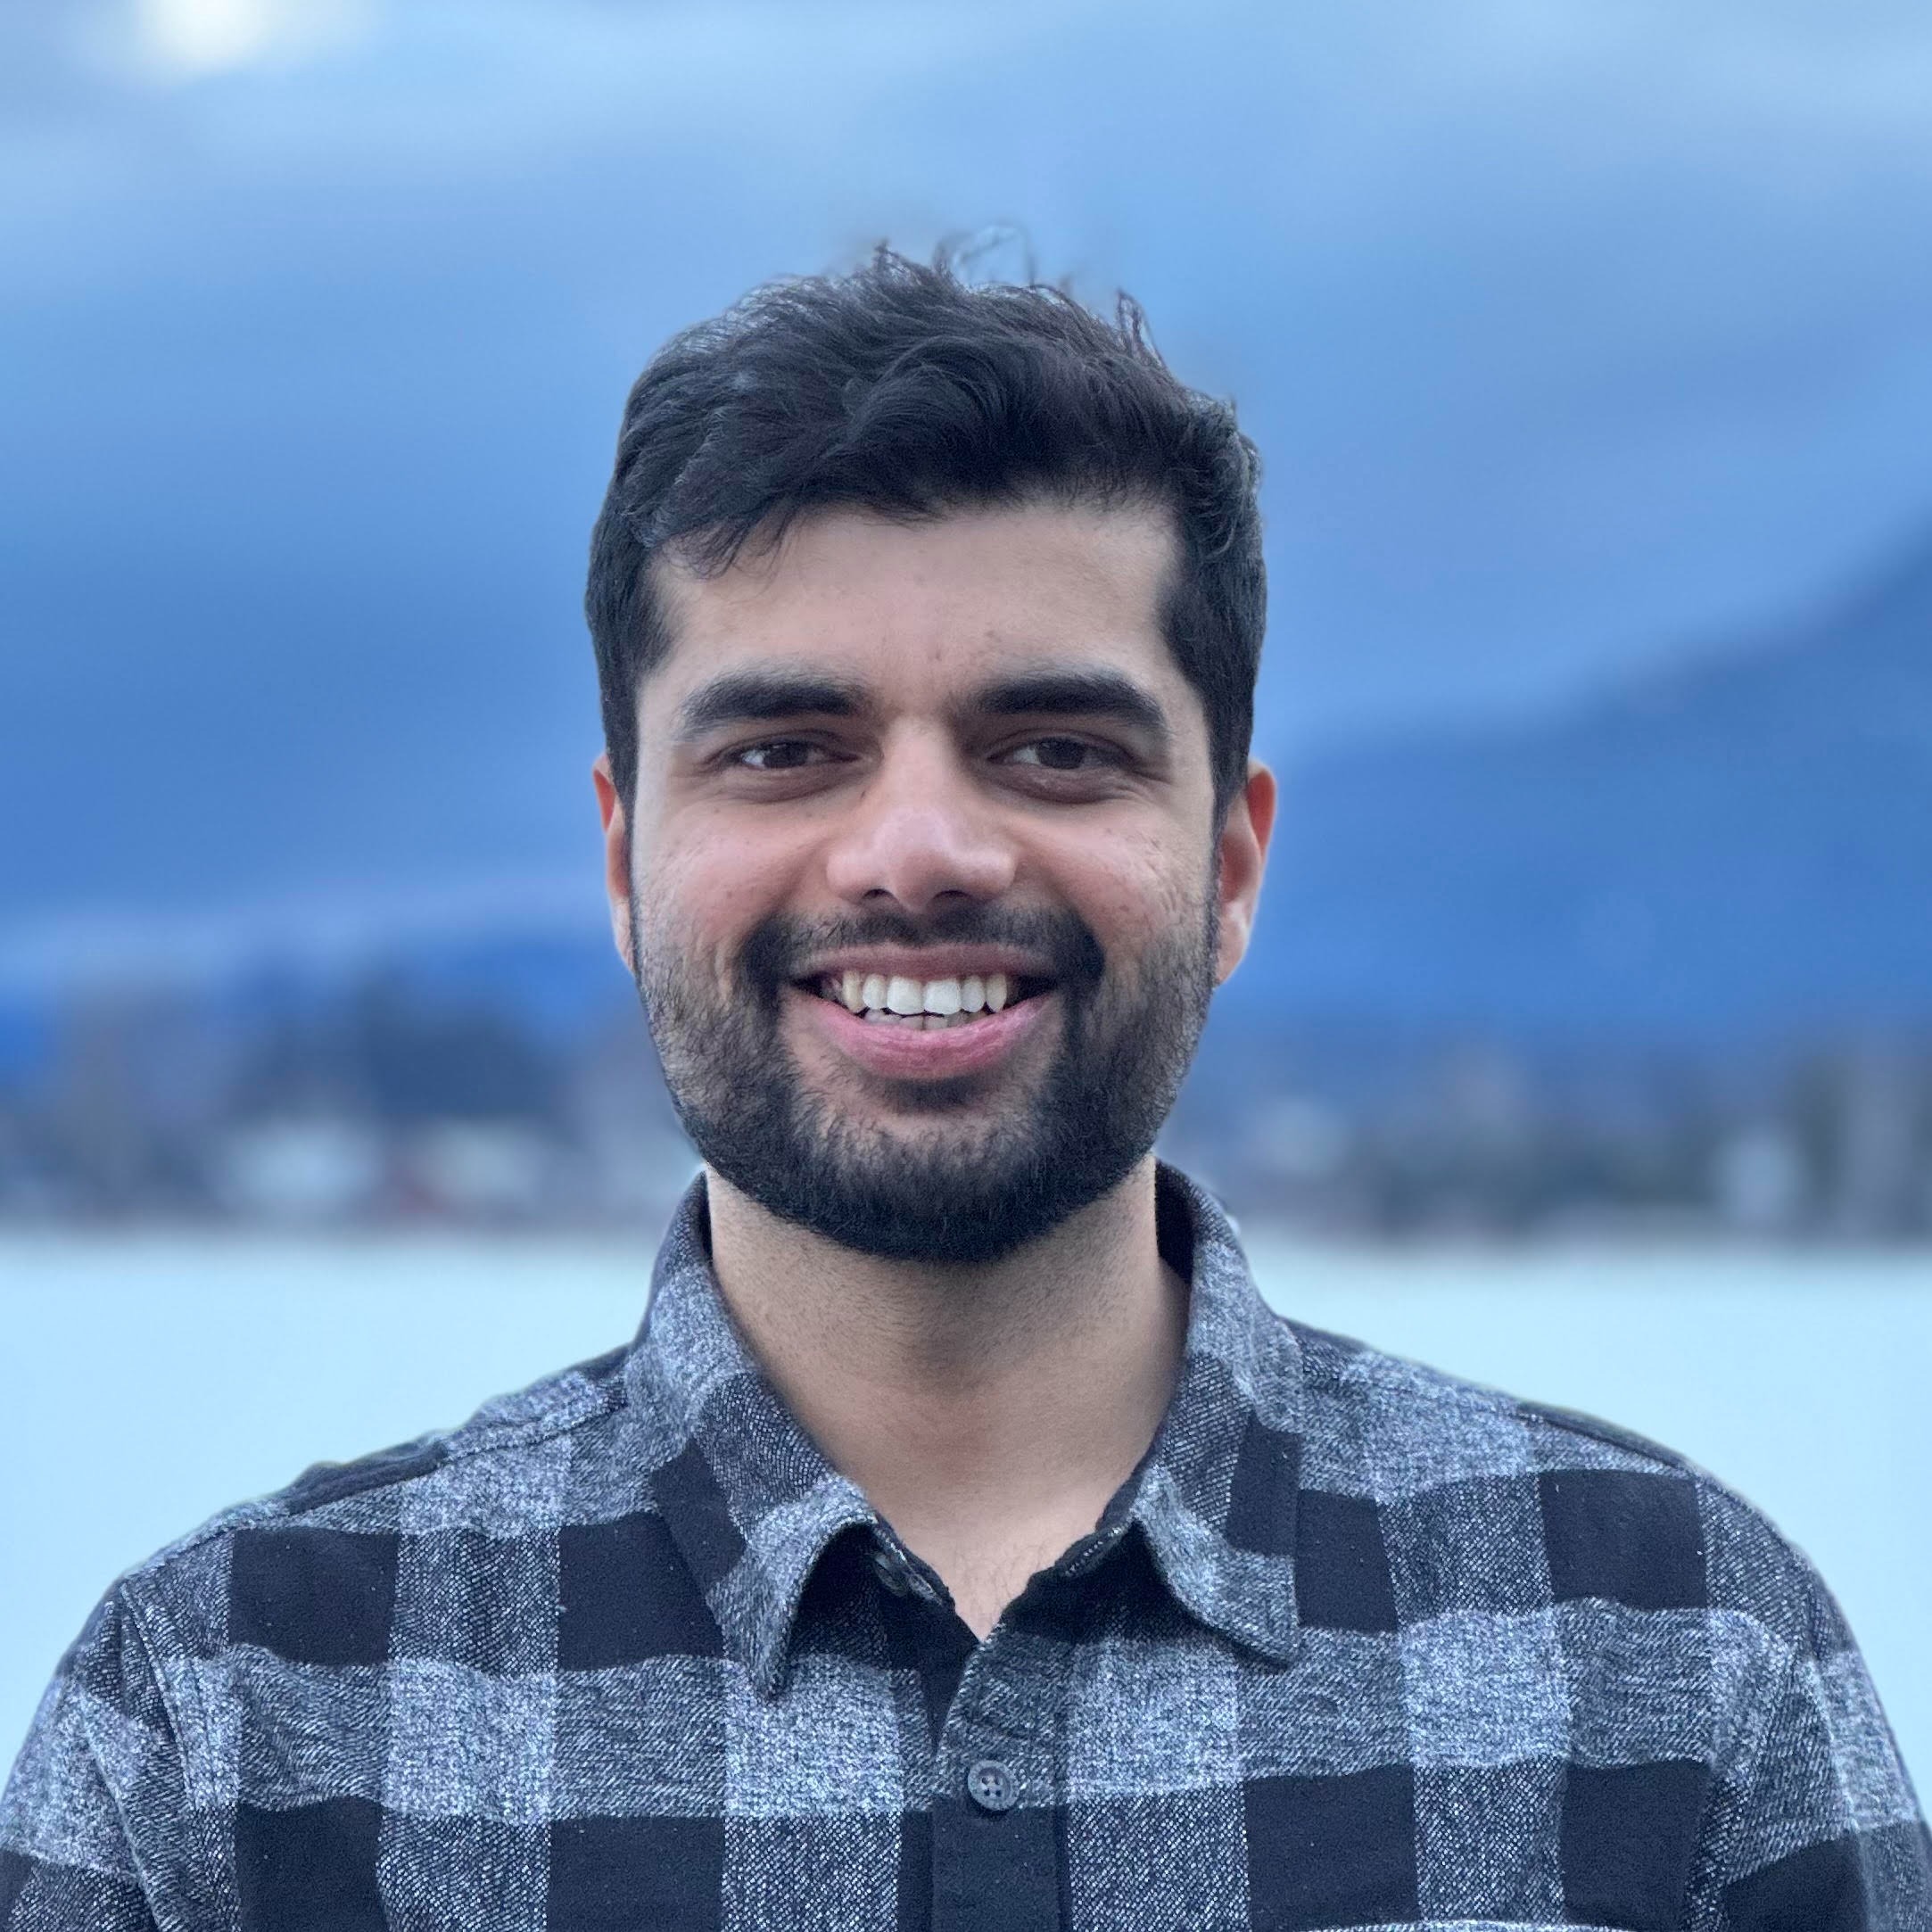
Piyush Kadam
Group Product Manager, Crusoe AI